


Things you might have missed
From our recent coverage:
Tencent’s AI capex nearly tripled. Second-quarter spending reached RMB52.8 billion ($7.3 billion), up 176% from a year earlier. President Liu Chiping said some compute orders could now be resold for more than 30% above what Tencent paid, giving the company an unusual cushion as it funds Hunyuan, WeChat AI and enterprise agents. Read more →
DeepSeek launched V4 Pro at three times Flash pricing. The official model keeps a one-million-token context window, raises maximum output to 384,000 tokens and adds agent and coding tools, while concurrency falls to 500 from Flash’s 2,500. See the breakdown →
SenseTime expects to return to profit. The company forecast first-half net income of RMB500 million to RMB700 million ($69 million to $97 million), compared with a RMB1.49 billion loss a year earlier, though its adjusted non-IFRS result remains a loss. Read the update →
AI That Predicts the Physical World
Chinese investors are moving unusually early and aggressively on world models. Startups only months old are raising large seed and Pre-A rounds, and several robotics companies announced nine-figure financings in the first half of 2026, often before releasing a model or identifying a commercial customer. It is a sharp departure from China’s first LLM wave in 2023, when early funding clustered around a relatively small group of established founders and major technology companies.
The scale of the shift is already visible in the money. The world-model companies tracked in this article had disclosed at least $1.44 billion by Aug. 17, 2026, with several additional rounds reported only as ranges. By comparison, Qianzhan Industry Research Institute, using ITJuzi records, counted 20 Chinese LLM financings worth RMB6.427 billion ($950 million) during all of 2023.
The rush comes as robotics itself is reaching an inflection point. Better generative video and simulation can create far more material for robots to learn from, while improving robot-control systems have made the ability to predict what happens after a machine acts a more obvious missing piece. Hardware is getting cheaper, more robots are moving into real workplaces, and engineers who spent years building autonomous-driving systems are moving into embodied AI.
Beijing is adding fuel. China’s 15th Five-Year Plan does not use the term “world model,” but it backs embodied intelligence as a route toward general AI and identifies it as a future industry the government wants to develop into a new source of growth. The 2026 national economic plan also calls for more venture and angel investment in future industries and for state guidance funds to invest earlier, for longer and in hard technology.
Models are appearing almost as quickly as the financing. During June and July alone, Chinese teams released at least eight named systems or major versions, including offerings from Alibaba and Xiaomi, in a category that barely existed as a distinct Chinese startup label a year earlier.
What investors are buying is the possibility of bringing some of the flexibility of LLMs into the physical world. A world model tries to learn how objects, people and machines change over time, then predict what might happen after a robot takes a particular action. If that works across different tasks and machines, robots could practice and make mistakes virtually, anticipate the consequences of their movements and rely less on expensive physical trial and error.
That remains well ahead of what the technology can do today. Current models can generate convincing videos while getting the physics wrong, and performance can deteriorate when the robot, camera or environment changes. Investors are putting billions behind the idea that world models could unlock more capable robots, long before anyone has proved they can reliably transfer from one machine, task or workplace to another.
What World Models Are
Some Chinese industry reports use “world model” broadly, spanning autonomous driving, humanoid robotics and video generation. This article uses a narrower definition: a world model predicts how the physical world could change after a possible action, allowing robot software to evaluate potential outcomes before deciding what to do. Autonomous-driving systems and entertainment video generators such as ByteDance’s Seedance are excluded, while video generation counts only when it is used to predict what happens around a robot, create training data or test control software.
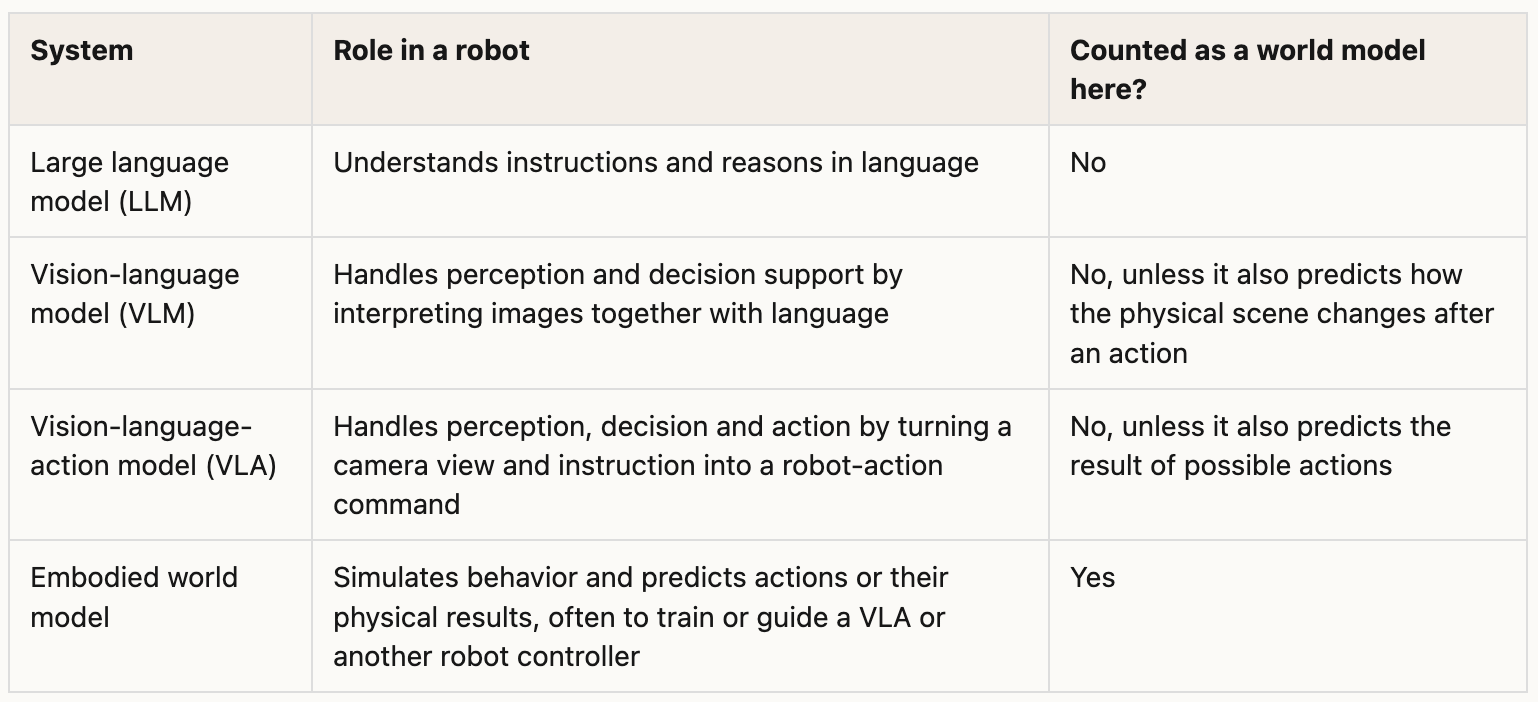
Alibaba shows how much broader the label has become. It released four systems under the world-model name in a single week in June 2026, but only Qwen-RobotWorld predicts future robot scenes and falls within the scope of this article. DreamX-World and HappyOyster generate digital environments for people to explore, while Qwen-AgentWorld models software environments.
For robotics, world models are most useful today during training, where they can create variations of recorded demonstrations or virtual environments for robot software to practice in. Some are also beginning to predict what could happen after different movements while a robot is operating, though so far only on narrow tasks. The world model typically does not control the robot itself. That job usually falls to a vision-language-action model, or VLA, which turns what the robot sees and is told into movement commands, or to another control system.
Chinese industry analysts often describe these technologies as parts of the same stack. Language and vision-language models help a robot understand its surroundings and decide what needs to happen, VLAs translate those decisions into actions, and world models try to anticipate the consequences. The longer-term goal is a continuous loop in which the robot predicts, acts, sees what actually happened and uses that information to improve its next decision. Researchers have demonstrated pieces of this process on narrow tasks, but not a general system that can do it reliably across different robots and environments.
A Brief History
World models predate the recent boom in AI-generated video. Their roots are in model-based planning and reinforcement learning, where researchers built simplified internal representations of an environment so software could test possible actions without trying every option in the real world.
The term gained wider attention in 2018, when AI researchers David Ha and Jürgen Schmidhuber published World Models. Their work showed that an AI system could learn and practice inside its own simplified simulation, while also exposing a problem that remains central today: if the simulation gets reality wrong, the AI can learn strategies that work in its imagined world but fail in the real one.
From 2019 onward, Dreamer, a research program now associated with Google DeepMind, developed the internal-prediction approach further. Rather than recreating every possible future as a complete image, Dreamer learns a compressed representation of its environment and uses it to imagine the consequences of different actions. The research has continued through several generations, including DreamerV3, published in Nature in 2025.
Advances in generative AI since 2023 have brought another set of approaches into the field, using video generation and interactive simulation to model possible futures more explicitly. Google DeepMind’s Genie generates interactive virtual environments, while Meta’s V-JEPA follows the older approach of predicting future states without generating full video. NVIDIA’s Cosmos spans world models and tools for physical AI, and Chinese developers are now pursuing many of the same approaches with robotics as the target.
World-model research has thus arrived at robotics from two directions: one built around predicting the future internally, and another around generating increasingly realistic versions of what that future could look like. They are converging on the same goal of helping a robot anticipate what could happen before it acts, then learn from what actually happens afterward.
How Do You Measure a World Model?
World models do not yet have anything like the scorecard investors use for LLMs. Language models can be compared, however imperfectly, by parameters, training tokens, context length, speed, price and standardized benchmarks. World-model developers disclose a far less consistent mix of model sizes, hours of video and robot demonstrations, simulation, computing resources, latency and task results. Comparable pricing barely exists because most systems are not yet commercial products.
Even familiar measures such as parameter count can be deceptive because the models work in fundamentally different ways. Xiaomi’s U0 has 38 billion parameters and learns partly by predicting what comes next in images and video. Meta’s V-JEPA 2 has just 1.2 billion, but instead predicts a compressed representation of what might happen without generating the full future as video. Meta trained the model on more than one million hours of internet video, then used less than 62 hours of robot data to adapt it for robot planning. AgiBot has disclosed a 1.6 billion-parameter version of Genie Envisioner. The numbers are precise, but putting them side by side says surprisingly little about which model is better.
Robot performance offers a more meaningful comparison, though even here the tests measure different levels of difficulty. A model might generate a believable video of what happens next, use those predictions to improve a robot during training, or go further and help a robot decide what to do while it is actually operating.
Chinese models have performed well at the first task. In WorldArena 2.0 results retrieved on Aug. 17, FlowWAM-FiveAges and Xiaomi’s U0 ranked first and second for generated robot video, with several other Chinese systems also scoring highly. But a video that looks right can still be physically wrong. A gripper might appear to approach a cup perfectly while stopping just far enough away that the real robot could not pick it up.
That does not make generated video useless. Xiaomi reported that adding training examples created by U0 raised the success rate of separate robot-control software from 36.9% to 63.2% in its test of unfamiliar conditions. U0 was providing more examples for the robot to learn from rather than controlling it directly, and the improvement has not been independently demonstrated across different robots or customer sites.
The harder step is using prediction while the robot is actually working. Meta reported that V-JEPA 2 achieved 65% to 80% success on selected pick-and-place tasks after additional training on less than 62 hours of robot data. Because V-JEPA 2 predicts internally, it does not need to generate a video of every possible move before the robot acts. The tests included two labs where training data had not been collected, providing evidence that the approach can carry into new environments, although the tasks remained narrow.
NVIDIA has reported another promising result from its broader Cosmos 3 system. A robot-control model developed from Cosmos 3 averaged 39.7% success across the 120-task RoboLab benchmark under specific task instructions, compared with 28.1% for Physical Intelligence’s π0.5 and 25.2% for DreamZero. The comparison is not clean, however, because Cosmos combines world modeling with other control technology, making it difficult to isolate how much of the improvement came from the world model itself.
For now, the industry has plenty of numbers but no common yardstick. The measures that ultimately matter may be more practical than parameters or benchmark rankings: whether a world model makes a robot more successful, reduces expensive physical training, carries what it learns to different robots and workplaces, and does so quickly and cheaply enough to be worth using.
The Field Takes Shape
China’s world-model industry has been assembled at remarkable speed. RobotEra was already experimenting with predictive robot models in 2024, but nine of the 12 developers tracked below released their first listed system in 2026, seven of them between April and July. What was recently a research direction scattered across robotics labs is now attracting startups, major technology companies and some of China’s best-funded new robotics teams.
(Below is a Robot Era robot sorting packages at a facility in Guangzhou. Tech Buzz China visited Robot Era this summer and can confirm this demo is not enhanced in any way.)
That compression is important because the companies are raising money almost as quickly as they are releasing models. Investors are backing teams before there is much evidence about which technical approach will travel beyond controlled experiments, where world models will ultimately fit in the robotics stack or whether customers will pay for them separately at all. The result is a market in which company formation, model releases and financing are happening almost simultaneously.
A selection of publicly named Chinese embodied world models
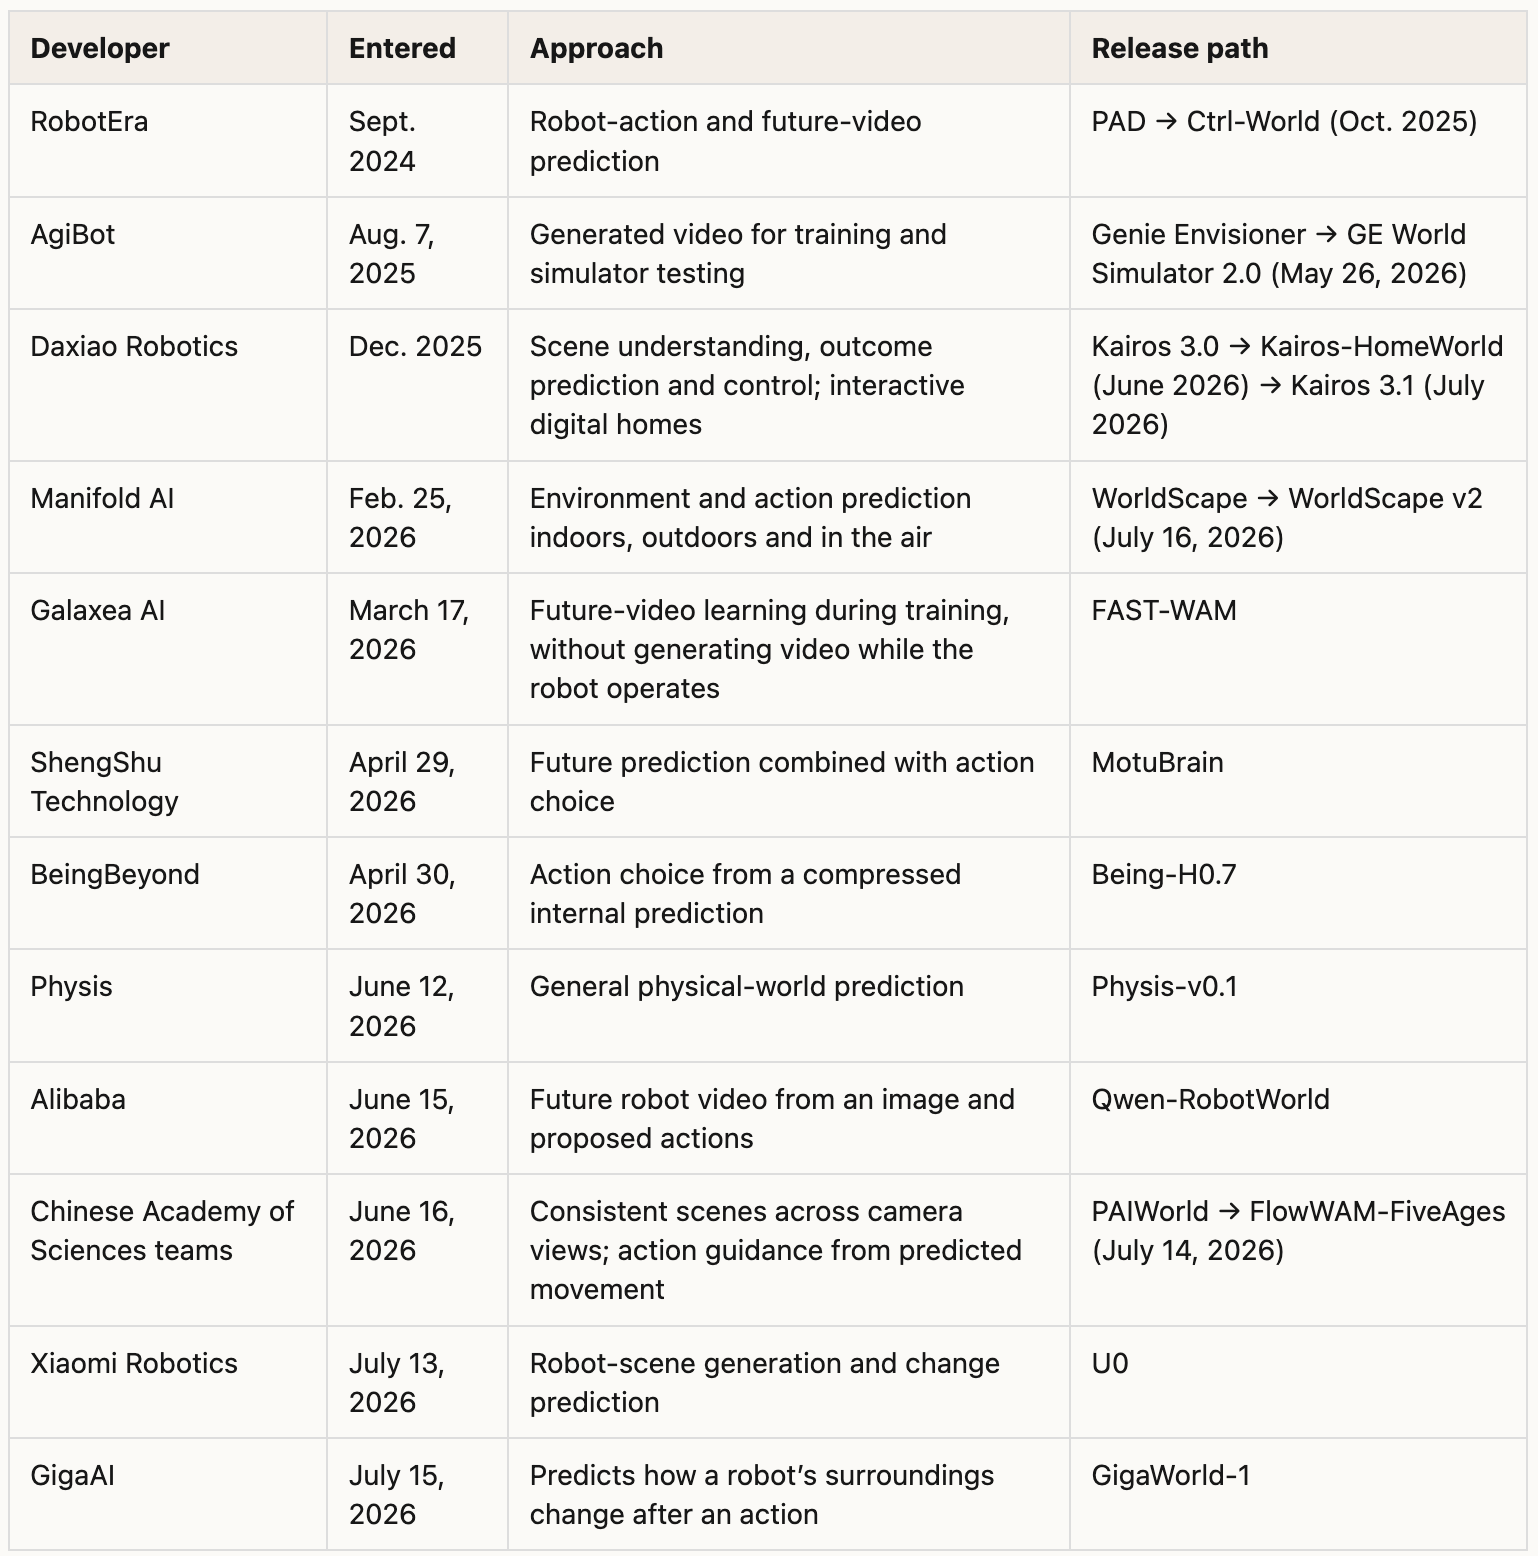
The speed of the fundraising is even more striking. GigaAI raised RMB3.5 billion (about $490 million) across rounds in March, April and June 2026. Manifold AI accumulated nearly RMB1 billion (about $140 million) in Pre-A financing across six rounds by June, while Physis went from a first financing of more than $10 million in March to a seed++ round exceeding $100 million in June. KunlunX raised several billion renminbi across three rounds within three months of incorporation.